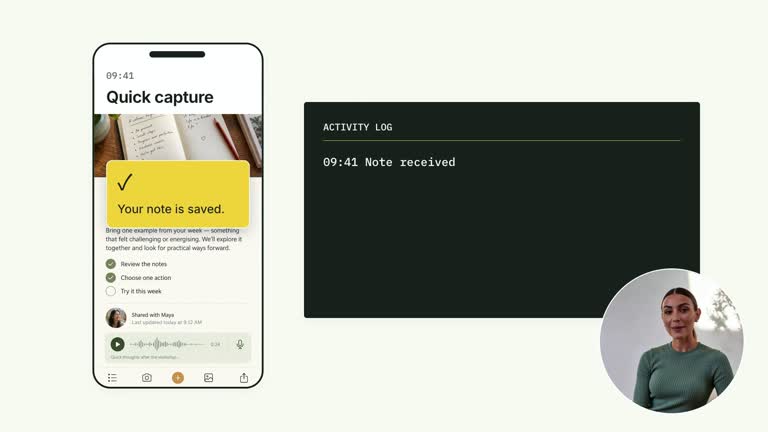
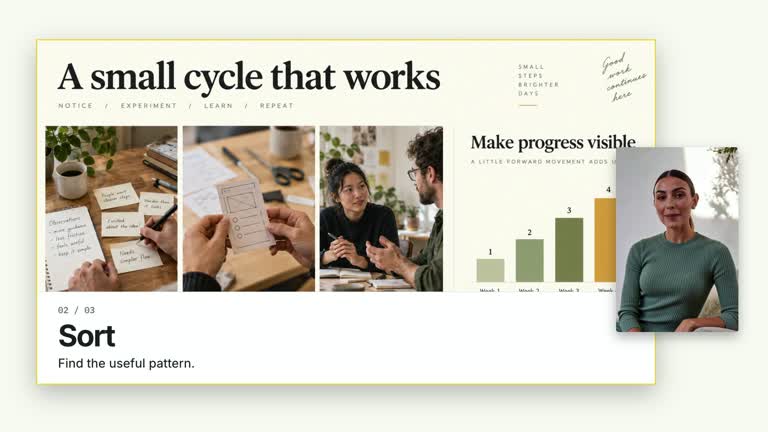
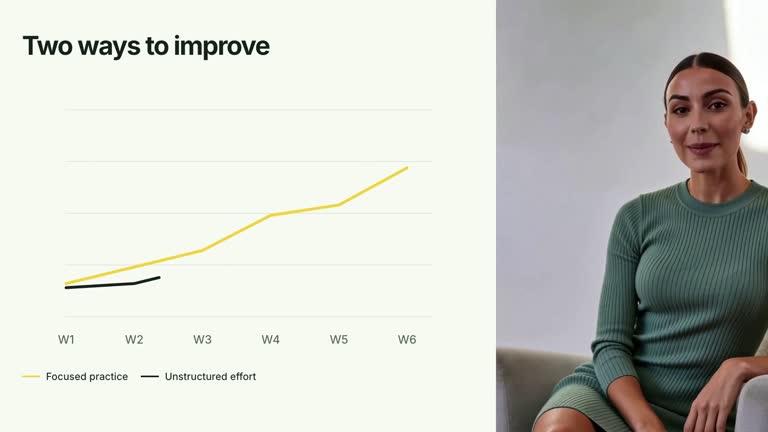
Present one short exchange inside a page while a supplied speaker remains visible. The question, finite waiting-dot sequence and answer reveal form separate beats; the surrounding page then pushes in gently during the reading interval. This 6.8-second scene animates prepared dialogue without sending a prompt to an AI model or generating a reply.
What you get
A local generator, editable HyperFrames page/chat/presenter composition and motion/review instructions for a 1920×1080, 30 fps segment. Generate and render the explanation with your own content and local video.
pageTitle, question and reply inputs. page-image and chat-avatar raster slots have bundled defaults, while the continuous presenter take is supplied separately. Page chrome and supporting introductory wording are authored in the scene.
Page and presenter establishment, question reveal from 0.65 seconds, waiting dots from 1.20 seconds and a reply reveal from 2.34 seconds after the waiting state fades. A restrained page-scale push runs from 2.70 seconds through the final reading interval.
Four styles keep the same data and choreography: White & Yellow (white-yellow), Charcoal & Lime (charcoal-lime), Paper & Orange (paper-orange), and Black & White (midnight-ice). Semantic style overrides are supported; check contrast after changing them. Dark canvases use a fine grid. Local fonts include Inter, IBM Plex Mono for measurements and ordinals, Smiley Sans and Noto Sans SC. Chinese text selects Smiley Sans automatically, including accompanying Latin text; --zh-font noto-sans-sc selects Noto Sans SC, while --font takes precedence for a supplied font.
Before you choose
Prepare an answer worth reading before designing its reveal. Use the waiting beat to explain the exchange, while keeping simulated dialogue distinct from a tested model response or verified recommendation.
Good fit
A creator explaining one concise question/answer exchange while maintaining page context and a visible speaker.
A teaching passage needing a clear distinction between asking, waiting and reading the answer.
A series using consistent page imagery, conversation styling and presenter crops.
Not for
Calling a chatbot, generating answers, observing actual response latency or validating the supplied advice.
Long multi-turn conversations, a working website/chat application or automatic narration synchronization.
Automatic full-film editing, creation of missing presenter performances or music, or copying another creator’s identity and source material.
How to use
You say/creatormotion-pip-chat-response Turn my supplied explanation into a white-yellow B-roll scene using the Chat Response Presenter effect. Use the text, data and media I provide, and ask for any required input that is missing.
Write pageTitle, a short question and a concise reply in JSON. Treat reply as copy you must prepare and verify; no model call derives it from the question. Long dialogue needs a layout/timing change rather than relying on automatic fit.
Supply a continuous local presenter clip of at least 6.8 seconds through --media. The video is muted and shown with a strong circular crop/zoom. Inspect face framing and whether the speaker overlaps the reply area; do not loop a short take. No alpha matte is used.
Reuse page-image and chat-avatar or replace named slots through --images MAP.json, with relative paths resolved beside the map. These still images are separate from the speaker video. Keep material relevant and follow the image policy; defaults are illustrative rather than evidence of an actual exchange.
Prepare Node.js 22+, FFmpeg and HyperFrames CLI 0.8.30. From the extracted package run node scripts/create.mjs --out /absolute/PROJECT --data /absolute/CONTENT.json --style white-yellow --media /absolute/PRESENTER.mp4. Use another documented palette or semantic --overrides as needed. Read the motion specification, DESIGN.md and image policy before adapting materials.
Run the generated project’s lint, validate and inspect checks, then render with the printed command. Inspect actual MP4 frames at entry, every focus change and the final reading hold for seams, clipping, contrast and media overlap. Keep essential text and interface targets readable; compare all four palettes with identical content after module changes. Narration is separate, and a silent preview does not establish audio synchronization. Inspect the question, waiting-dot stop and answer handoff, then the page push and final reply fit. Keep enough still reading time for the actual answer and do not add decorative motion that distracts from the exchange.
Requirements and costs
You bring
pageTitle: provide your own content or retain the illustrative default. · question: provide your own content or retain the illustrative default. · reply: provide your own content or retain the illustrative default.
Dependencies
HyperFrames CLI 0.8.30 or compatible — required · Node.js 22 or newer — required · FFmpeg — required
Outside costs
Not collected yet
Tools used
HyperFrames
Publisher testing
v1.0.1 — Claude Code / Claude Desktop / Cowork / Codex / ChatGPT
FAQ
Yes. pageTitle, question and reply are JSON inputs, with four palettes and semantic overrides. Fixed page headings and introductory copy are in the effect code rather than separate content fields.
Yes. The composition expects a continuous local presenter take covering 6.8 seconds. Default page/avatar rasters are included; they do not replace the video. This is a circular video crop, not a matte-based cutout.
Yes. Preserve distinct question, finite waiting and reply beats, followed by the subtle page push. Re-render after timing or dialogue changes and check actual transition frames and the final reading interval.
No. You supply reply. The waiting dots and answer reveal are predetermined visual beats, not a request to an AI service.
No. It is authored timing. A rendered preview illustrates a conversation and does not demonstrate model speed or service latency.
User reviews
—0 reviews
Select a star to share your experience.
No reviews yet. Ratings appear once readers share real experiences.