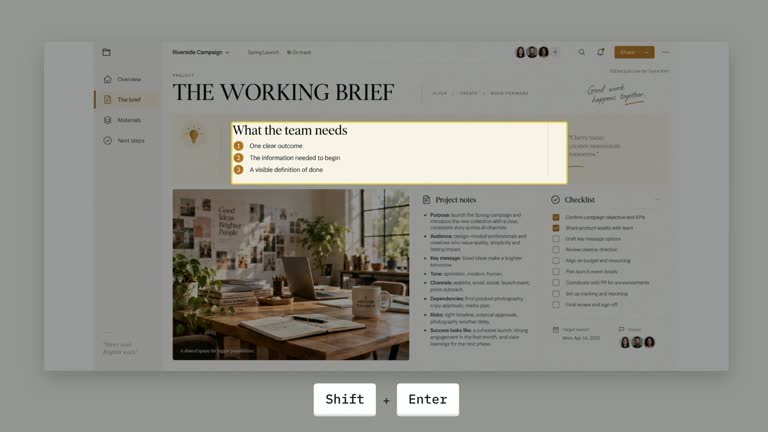
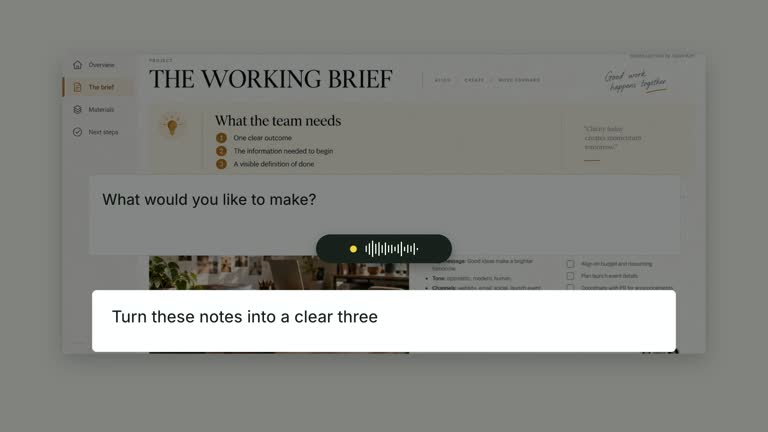
Focus one region of a document, explain it with a connected note, then restore the full context. The document and annotations move together in a short push so their relationship stays registered; a separate step footer remains as the focus clears. This nine-second scene uses a supplied image and rectangle rather than detecting the important content itself.
What you get
A local generator, editable HyperFrames document/annotation shot and motion/review instructions for a 1920×1080, 30 fps segment. Generate and render a focused explanation from your image and copy.
region as normalized [x,y,width,height], callout and step. The canonical document raster slot has a bundled default. Legacy documentTitle, sectionTitle and rules fields remain compatible inputs but do not rewrite the required raster source.
An outside-region scrim and group push from 0.65 seconds, a connected leader from 1.10 seconds and note/footer from 1.45/1.70 seconds. Focus treatments clear from 6.70 seconds and the group returns to full scale from 6.80 seconds.
Four styles keep the same data and choreography: White & Yellow (white-yellow), Charcoal & Lime (charcoal-lime), Paper & Orange (paper-orange), and Black & White (midnight-ice). Semantic style overrides are supported; check contrast after changing them. Dark canvases use a fine grid. Local fonts include Inter, IBM Plex Mono for measurements and ordinals, Smiley Sans and Noto Sans SC. Chinese text selects Smiley Sans automatically, including accompanying Latin text; --zh-font noto-sans-sc selects Noto Sans SC, while --font takes precedence for a supplied font.
Before you choose
Select a region that makes the note verifiable from the visible source. Check the restored view as carefully as the close focus so the annotation clarifies context rather than concealing it.
Good fit
A creator explaining one specific section of a document while maintaining its surrounding context.
A teaching passage where the annotation should resolve back to a full-view document rather than end on a permanent crop.
A series using consistent source framing, normalized rectangles and concise step footers.
Not for
Automatically selecting a region, reading the document or changing text baked into the screenshot.
A multi-region inspection sequence, arbitrary annotation layouts or treating legacy title/rule fields as active raster editing.
Automatic full-film editing, generated presenter footage or music, or copying another creator’s identity and source material.
How to use
You say/creatormotion-spotlight-region-callout Turn my supplied explanation into a white-yellow B-roll scene using the Region Callout effect. Use the text, data and media I provide, and ask for any required input that is missing.
Choose a meaningful document region and write a short callout and step footer. region uses normalized x/y/width/height within the 1600×710 display panel. Use positive dimensions and check the rectangle against the visible image, including any contain-fit margins.
Reuse the bundled document or replace the canonical document slot through --images MAP.json, with relative paths resolved beside the map. The image is required. Change the raster itself when its title, sections or rules need editing; the legacy fields cannot rewrite embedded words.
Recalibrate the region after every screenshot change. The leader connects by authored geometry, not OCR or content recognition. No presenter or matte is used; the complete image, note and annotations move as one group during the small camera push.
From the extracted package, prepare Node.js 22+, FFmpeg and HyperFrames CLI 0.8.30. Run node scripts/create.mjs --out PROJECT --data CONTENT.json --style white-yellow, substituting another documented palette if wanted. Read the motion specification and image policy before adapting the scene; use semantic --overrides for deliberate style changes.
Inspect the editable project at entry, each motion handoff and final hold, then render with the command printed by the generator. Check the resulting frames for text collisions, correct numbers and readable contrast. Keep at least 1.2 seconds for the final reading when editing, and compare all four palettes with identical content after structural changes. Narration, music and assembly into a longer film remain separate work. Inspect all four scrim edges, target boundary, leader endpoint and note in actual MP4 frames. Confirm full context returns cleanly while the step footer remains. Keep essential text readable and preserve at least 1.2 seconds of final reading after edits.
Requirements and costs
You bring
region: provide your own content or retain the illustrative default. · callout: provide your own content or retain the illustrative default. · step: provide your own content or retain the illustrative default. · documentTitle: provide your own content or retain the illustrative default. · sectionTitle: provide your own content or retain the illustrative default. · rules: provide your own content or retain the illustrative default.
Dependencies
HyperFrames CLI 0.8.30 or compatible — required · Node.js 22 or newer — required · FFmpeg — required
Outside costs
Not collected yet
Tools used
HyperFrames
Publisher testing
v1.0.1 — Claude Code / Claude Desktop / Cowork / Codex / ChatGPT
FAQ
Yes. callout and step are editable text, region controls the geometry, and palettes/semantic overrides change appearance. documentTitle, sectionTitle and rules do not rewrite the raster document.
No. A document raster is required and has a bundled default; replace it locally when needed. This implementation uses no presenter video or alpha matte.
Yes. Preserve source/context, regional focus, connected note and full-view restoration. Re-render after image or rectangle changes and keep the source/annotation camera group aligned.
No. You supply the rectangle and explanatory note. The scene does not read or analyze the document.
That field is retained for legacy compatibility, while the active source is a required raster. Replace document when changing text already embedded in the image.
User reviews
—0 reviews
Select a star to share your experience.
No reviews yet. Ratings appear once readers share real experiences.